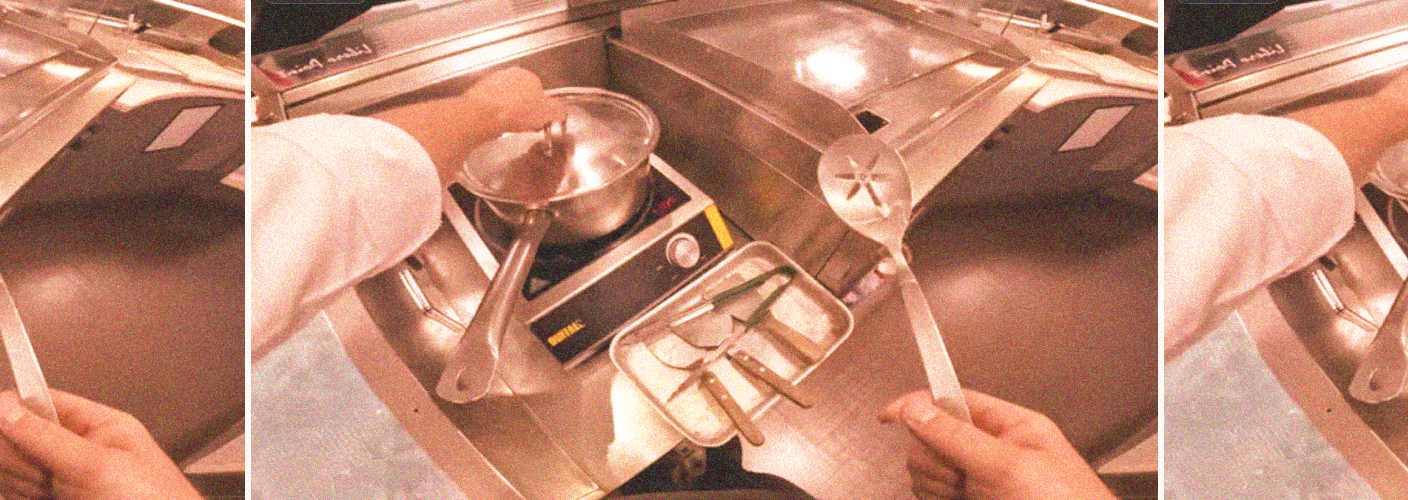
TL;DR: Body camera footage and crowdsourced egocentric video both produce first-person data, but they don't scale the same way. Issued hardware caps coverage at whatever a program can fund; a verified, validated contributor network scales with how many contributors can be coordinated - and that difference is what actually shows up in how well a model generalizes.
Every physical AI team eventually hits the same wall: the first-person dataset that worked for the demo doesn't hold up once the model has to operate somewhere it wasn't trained. New lighting, new layout, new body doing the task - and the model that looked ready in the lab starts guessing.
That wall is usually a sourcing problem before it's a modeling problem. Two approaches dominate how teams get first-person video into their training pipeline, and they scale in almost opposite directions.
Two ways to source first-person video
The first is dedicated hardware programs - body-worn cameras issued to a fixed group of wearers, recording within a defined set of environments and tasks. The second is distributed, crowdsourced capture - sourcing footage from a broad, verified network of contributors using devices already in their hands, across many more locations and situations than any issued-hardware program could reach. Both produce first-person videos. They don't produce it at the same scale, and they don't produce the same kind of diversity.
Where dedicated body camera programs fall short for AI training
Issued-hardware programs are built for a narrow operational purpose, and that shows up in the resulting data. Coverage is capped by how many devices and wearers a program can support, footage skews heavily toward whatever environments those wearers actually operate in, and hardware and logistics costs scale linearly with every additional wearer or region added. None of that is a criticism of the hardware - it's simply optimized for a different job than training a generalizable AI model. Datasets that lack variance across environments and situations tend to bias the resulting model toward whatever narrow distribution it sees most often, which is precisely the failure mode a growing physical AI program is trying to avoid. A dataset that's technically first-person isn't automatically a dataset that generalizes.
What scaled crowdsourcing actually solves
Crowdsourced capture flips the constraint. Instead of a fixed set of issued devices, footage comes from a distributed contributor network large enough to cover far more environments, tasks, and demographics than any single hardware program could fund. The ceiling on scale moves from "how many cameras can we issue" to "how many verified contributors can we coordinate and validate."
That second question is the harder one to answer well - we cover how teams manage that process in building and managing annotation teams for crowdsourced data.
How Humyn Labs approaches egocentric video at scale
Humyn Labs runs the complete physical AI data pipeline on crowdsourced egocentric footage - collection, validation, multilayer quality control, annotation, and human-in-the-loop review. As an independent multimodal human data company, Humyn Labs runs the complete pipeline on crowdsourced egocentric footage rather than treating collection alone as the deliverable. Clients work with a verified first-party contributor network built specifically for the task at hand, not a raw pool of individual collectors, which means the diversity crowdsourcing makes possible doesn't come at the cost of the consistency a training pipeline actually needs.
That network's geographic reach, including contributors across the Global South and in low-resource-language regions, is itself part of the answer to the generalization problem: a model only avoids guessing in unfamiliar settings if unfamiliar settings were part of what it learned from. Scale without validation is just more unlabeled risk. Scale with a pipeline behind it is a dataset a model can actually trust.
Key Takeaways:
1.Body camera footage is capped by hardware and wearer count; crowdsourced egocentric video scales with the contributor network
2.Issued-hardware programs skew toward the narrow environments their wearers operate in, which biases the resulting model
3.A technically first-person dataset isn't automatically one that generalizes
4.Crowdsourcing moves the ceiling from hardware to coordination — a far higher limit
5.Volume without validation shifts the diversity problem into a noise problem; the pipeline matters as much as the footage
6.Geographic reach across the Global South and low-resource-language regions is part of the generalization answer
FAQs
1. What's the difference between body camera footage and crowdsourced egocentric video?
Body camera footage comes from a fixed, issued-hardware program operating in a defined set of environments. Crowdsourced egocentric video comes from a distributed network of contributors using their own devices across a much wider range of locations and tasks.
2. Why doesn't body camera footage generalize well for AI training?
Coverage is capped by however many devices and wearers a program can support, so the footage skews toward whatever environments those wearers actually operate in. A model trained on that narrow distribution tends to perform well in similar settings and poorly everywhere else.
3. Does crowdsourcing sacrifice data quality for scale?
Not if there's a validation process behind it. Sourcing volume without quality control just moves the diversity problem into a noise problem - the pipeline around the footage matters as much as the footage itself.
4. What makes a crowdsourced contributor network different from a raw pool of collectors?
A verified, first-party contributor network is built and vetted for a specific task, not an open crowd platform. Clients work with validated data, not individual collectors directly.
5. Why does egocentric data diversity matter more than volume alone?
A model only avoids guessing in unfamiliar settings if unfamiliar settings were part of what it learned from. Volume without variation just produces more data from the same narrow distribution.
6. Can crowdsourced video reach the scale a physical AI program actually needs?
Yes - the ceiling shifts from "how many cameras can we issue" to "how many verified contributors can we coordinate and validate," which is a far higher ceiling than any hardware-issued program can reach.
7. How does Humyn Labs source egocentric video at scale?
Humyn Labs runs the full pipeline - collection, validation, multilayer quality control, annotation, and human-in-the-loop review - on footage sourced through a verified, first-party contributor network, including contributors across the Global South and low-resource-language regions.
More Articles
 ASR model comparison
Divyajot SinghSep 28, 20266 min read
ASR Models Have Different Failure Geometries
WER alone hides how ASR models fail. BRIDGE ASR 2.0 compares Gemini, GPT-4o, Saaras & Scribe on Indic, code-switched speech by error type.
Read Article→ WER
Debashish GhoshSep 3, 20263 min read
A transcript that was perfect — yet scored 15% wrong
A perfect transcript can still fail a WER test when code-switched words have two valid spellings. Here's how a normalization pipeline removes the scoring artifact.
Read Article→ what is supervised finetuning
Anoushka AnanthAug 27, 20266 min read
What Is Supervised Fine-Tuning? How It Trains Robot Foundation Models
Supervised fine-tuning is the stage that turns a pretrained VLA into a model that acts correctly. Here's how it works for robot foundation models.
Read Article→